trade-intelligence-copilot
Trade Intelligence Copilot
Ask a plain-English question about a year of Pakistani sugar import records, and this tool looks the answer up in the records themselves and shows the exact rows it used. When the records cannot support an answer, it says so instead of inventing one, the mistake most such tools make. It was graded on a 28-question test with answers computed from the records beforehand; every score, including its misses, is published below.
Verified end to end against a live Google Cloud Vertex AI project: ingestion, cited answers, the refusal path, and the full evaluation run were all exercised for real.
Overview
An agentic retrieval-augmented copilot over agricultural-trade data, with a real, published evaluation layer. Ask a plain-English question about Pakistani sugar-sector import data and get a grounded, cited answer, or an honest refusal when the data does not support one.
Key features
- Agentic planning that picks the right tools per question.
- Text-to-SQL passed through a read-only guard (single SELECT only, write and DDL keywords blocked, multiple statements rejected) on an immutable read-only SQLite connection.
- Grounded answers that cite the SQL query and rows, the HS-lookup rows, and the regulation chunks used.
- A deterministic no-evidence refusal path that fires before any synthesis call.
- A FastAPI service with POST /ask, GET /health, and a UI showing the answer, the tool-call trace, citations, and per-query cost and latency.
Results
| Metric | Result |
|---|---|
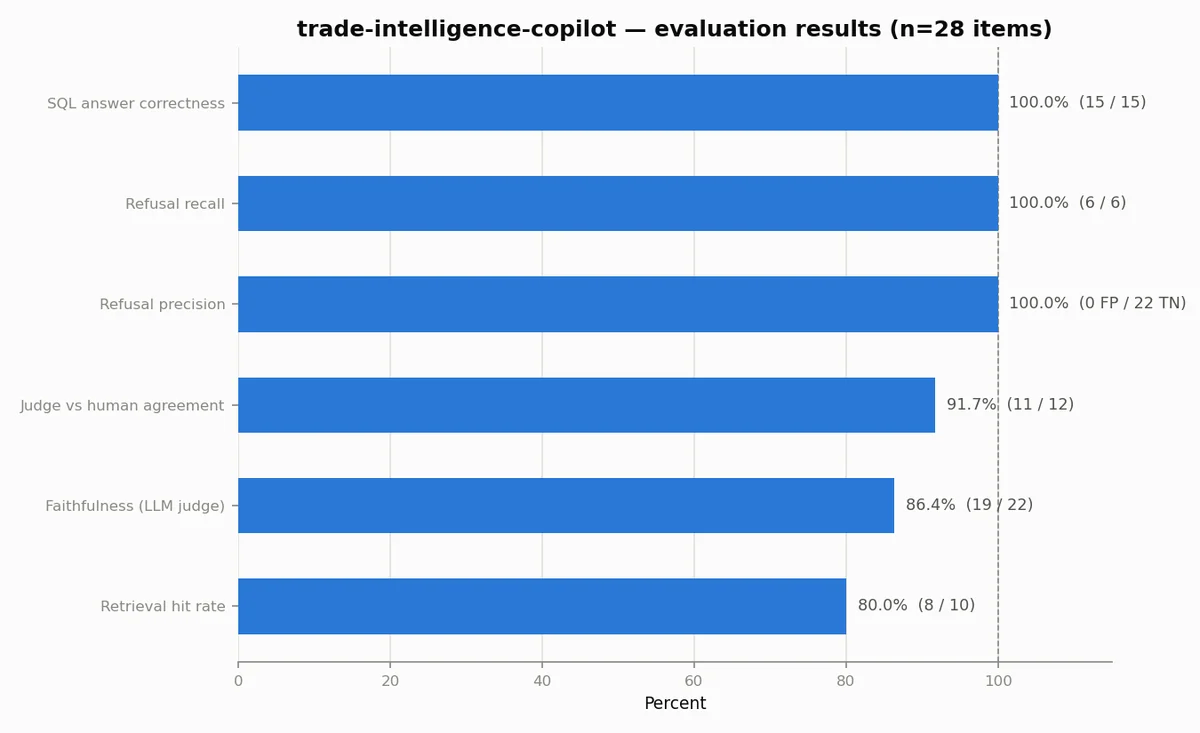
| SQL answer correctness (vs ground truth) | 15 / 15 = 100% |
| Retrieval hit rate | 8 / 10 = 80% |
| Refusal precision / recall | 1.00 / 1.00 |
| LLM-as-judge faithfulness (gemini-2.5-pro) | 21 / 22 = 95.5% |
| Judge vs independent labels (12 items) | 11 / 12 = 91.7% |
| Mean cost per query | $0.00093 |
| Latency p50 / p95 | 9.0 s / 27.0 s (8.8 s / 12.5 s without 3 rate-limited items) |
Reading the numbers honestly
SQL correctness is 100% only after an earlier fix. In the first version's first run the model matched a company name without wildcards and returned 0 shipments for an importer that had dozens; tightening the schema prompt fixed it, and the gold numbers are computed directly from the database.
The one faithfulness miss is a judgment call: asked about HS code 1702.1100 "(lactose)", the model gave the right count and repeated the question's own label, which the evidence rows never state. Independent labels count it faithful, since its one load-bearing claim, the count, is exactly the query result; it is the single disagreement in an 11-of-12 check of the judge. Latency p95 is inflated by rate limiting: three items waited out Vertex 429 responses. Refusal was perfect on this set, but the set is small, so read it as the path works, not it never fails.
Data
The trade data is synthetic: a seeded generator builds a compact SQLite database of made-up importers, suppliers and 2,000 import shipments across calendar 2025, so every run of the generator produces the same file and the test answers can be recomputed from it. Only the HS chapter 17 headings and the country names are real. The regulations corpus is 16 authored plain-language explainers written for this demo.